Yolo YOLO11 vs YOLOv8: Model Comparison A detailed expert comparison of YOLOv8 and YOLO11 object detection models, covering performance, accuracy, hardware needs, and practical recommendations for developers and researchers.
yolov12 Building a Pill Counting System with Labellerr and YOLO Fine-tuning YOLO for pill counting enables accurate detection and tracking of pills in pharmaceutical setups. Learn how to customize YOLO for your dataset to handle overlapping pills, varied lighting, and real-time counting tasks efficiently.
Product Update Product Update: September 2025 Greater Transparency and Control in Project Workflows This month’s release introduces enhancements to project creation, improved handling of grouped annotations, and new validation for object-type tasks. Together, these updates make project workflows faster, more transparent, and more reliable for annotators and reviewers. 1. Start Annotating Projects Immediately with Smarter
Product Update Product Update: August 2025 Advancing Precision in Video Annotation This month’s release focuses on improving video annotation workflows, enhancing SAM2 tracking, and adding finer control for editing. These updates are designed to make annotation more accurate, efficient, and user-friendly for both annotators and reviewers. 1. Frame-by-Frame Precision in Video Annotation to Eliminate Off-Sync
AI KOSMOS-2 Explained: Microsoft’s Multimodal Marvel KOSMOS-2 brings grounding to vision-language models, letting AI pinpoint visual regions based on text. In this blog, I explore how well it performs through real-world experiments and highlight both its promise and limitations in grounding and image understanding.
Vision Language Model BLIP Explained: Use It For VQA & Captioning BLIP (Bootstrapping Language‑Image Pre‑training) is a Vision‑Language Model that fuses image and text understanding. This blog dives into BLIP’s architecture, training tasks, and shows you how to set it up locally for captioning, visual QA, and cross‑modal retrieval.
SAM SAM Fine-Tuning Using LoRA Learn how to fine‑tune SAM with LoRA to achieve precise, domain‑specific segmentation without massive GPU costs. Freeze the SAM backbone, train only tiny low‑rank adapters, and deploy high‑accuracy models on modest hardware—fast, modular, and efficient.
object tracking OC-SORT Tutorial: Critical Insights You Can’t Miss! OC‑SORT claims improved occlusion and non‑linear motion handling by back‑filling virtual paths and using real detections, but its dependence on detector quality, straight‑line interpolation, and no appearance features can still lead to identity errors in dense or erratic scenes.
object tracking Track Objects Fast: BoT-SORT + YOLO Explained! BoT-SORT boosts multi-object tracking by refining box predictions, compensating for camera motion, and combining motion with appearance cues. Easily integrate it via Ultralytics YOLO or BoxMOT for robust tracking in crowded, dynamic scenes.
object tracking Track Crowds in Real-Time with FairMOT - A Detailed Tutorial FairMOT is a real-time, anchor-free tracking system that solves identity switch issues by combining object detection and re-identification in a single network, ideal for crowded scenes, surveillance, sports, and autonomous systems.
object tracking StrongSORT Tutorial: Master Multi-Object Tracking Learn what StrongSORT is, how it improves multi-object tracking, and how to easily implement it in your own projects using modern detectors like YOLO.
object tracking Learn DeepSORT: Real-Time Object Tracking Guide Learn to implement DeepSORT for robust multi-object tracking in videos. This guide covers setup, integration with detectors like YOLO for real-time use.
object tracking How to Implement ByteTrack for Multi-Object Tracking This blog shows code implementation of ByteTrack, combining high- and low-confidence detections to maintain consistent object IDs across frames. By matching strong detections first and “rescuing” weaker ones, it excels at tracking in cluttered or occluded scenes.
object segmentation MASA Implementation Guide: Track Objects in Video Using SAM MASA revolutionizes object tracking by combining the Segment Anything Model (SAM) with self-supervised matching. Track any object across video frames without category-specific training or manual labels. Learn how MASA works and implement state-of-the-art universal tracking in your projects.
Image Segmentation Learn SAM 2 in Minutes: The Ultimate Starter Guide for 2026 Learn to implement Meta's SAM2 for pixel-perfect image/video segmentation. Explore its zero-shot capabilities, real-time processing, and step-by-step code examples for bounding box & point-based object masking.
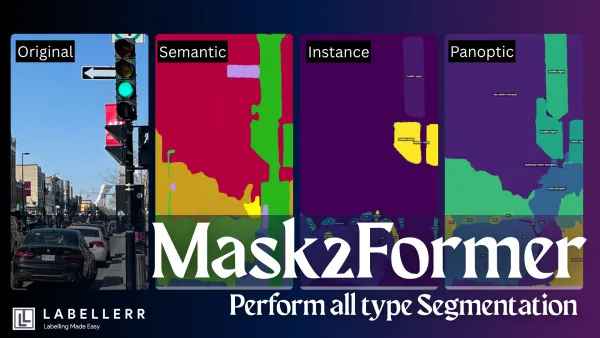
segmentation Mask2Former: Hands-on Tutorial Guide Learn how to perform semantic, instance, and panoptic segmentation using Mask2Former-a universal, efficient, and accurate model that streamlines image segmentation tasks across diverse applications.
segmentation SegGPT Demo + Code: Next-Gen Segmentation is Here SegGPT is a versatile, unified vision model that performs semantic, instance, panoptic, and niche-domain segmentation via in-context “color-in” prompting—no task-specific fine-tuning required, instantly adapting to new classes from just a few annotated examples.
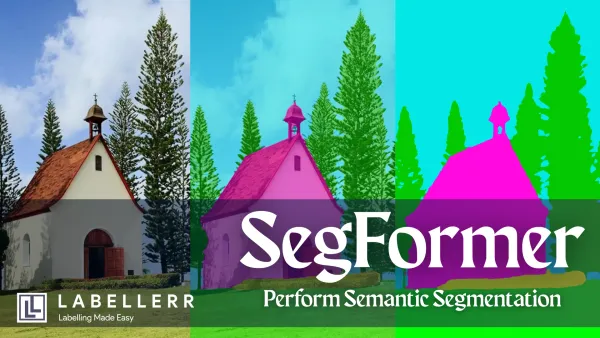
Semantic segmenatation SegFormer Tutorial: Master Semantic Segmentation Fast Learn how SegFormer uses Transformers and MLPs to perform semantic segmentation. Also implement Segformer yourself.
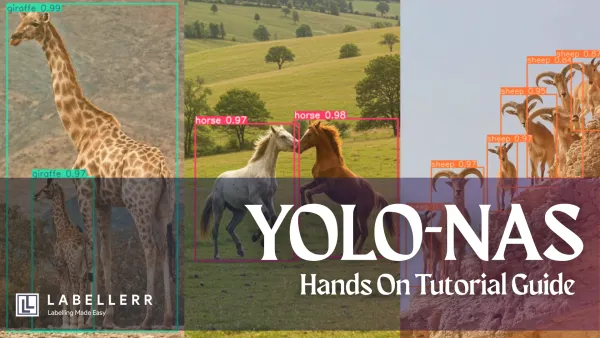
computer vision The Ultimate YOLO-NAS Guide (2026): What It Is & How to Use Explore YOLO-NAS! This guide explains its new Neural Architecture Search (NAS) for creating highly efficient and accurate object detection models for diverse hardware.
Yolo The Only YOLOv11 Multi-Labeling Guide You’ll Ever Need This guide details how to perform all vision tasks: detection, segmentation, pose estimation & more in YOLOv11.
Vision Agent Vision Agent Using SAM-Description-Based Object Segmentation Agent Build Vision Agents using Segment Anything (SAM)! Learn how to combine text descriptions (like with Grounding DINO) and SAM for powerful, zero-shot object segmentation, bypassing traditional training needs. Understand and build your own description-based vision agent.
object detection RT-DETRv2 Beats YOLO? Full Comparison + Tutorial Explore a comparison between RT-DETR and RT-DETRv2 in real-time object detection with transformer power. Learn how to implement it using HuggingFace.
computer vision How to Perform Object Detection Tasks Using OWL v2 Explore how to implement OWLv2, a powerful open-vocabulary object detection model. Learn about its zero-shot capabilities, classification, guided image query, and how it understands text and images together for real-world use.
computer vision How To Perform Vision Tasks Using Florence 2 Discover the way to perform various tasks Florence 2 can handle, from object detection to OCR using just prompts. Learn how this unified vision model simplifies complex workflows without sacrificing accuracy.
Ai in robotics How Data Annotation Is Powering The Humanoid Robots Data annotation is the foundation of robotics AI. From 3D labeling to semantic segmentation, it powers perception, navigation, and manipulation, helping robots see, understand, and interact with the world precisely and safely.